#7769 [DEBUG] 测试Google翻译测试返回status_code=0[WARNING] 检测google翻译失败:status_code=0,改为使用微软翻译[DEBUG] 以纯文本行形式翻译,每次翻译10行,翻译后暂停0.0s[DEBU

194.56**4 Posted at: 21 hours ago

image
[DEBUG] 测试Google翻译测试返回status_code=0
[WARNING] 检测google翻译失败:status_code=0,改为使用微软翻译
[DEBUG] 以纯文本行形式翻译,每次翻译10行,翻译后暂停0.0s
[DEBUG] 本次跳过翻译,使用缓存
[DEBUG] 本次跳过翻译,使用缓存
[DEBUG] 原始行数:11,翻译后行数:11
[DEBUG] 原始语言字幕和目标语言字幕行数一致,均为 source_len=11

[DEBUG] line_roles={}
[DEBUG] 语音克隆模式下,所用参考音频为:/Users/mac/pyvideotrans/tmp/73926/719b376297/clone_ref_44100.wav
[DEBUG] 裁切对应片段为参考音频:00:00:00,000->00:00:03,040
当前it={'text': 'Nước không phải là thứ duy nhất ở dưới đó.', 'line': 1, 'start_time': 0, 'end_time': 3040, 'startraw': '00:00:00,000', 'endraw': '00:00:03,040', 'ref_text': "The water's not the only thing down there.", 'start_time_source': 0, 'end_time_source': 3040, 'role': 'clone', 'rate': '+0%', 'volume': '+0%', 'pitch': '+0Hz', 'tts_type': 2, 'filename': '/Users/mac/pyvideotrans/tmp/73926/719b376297/0-25949b1203cef0e1020e925b43fdae72.wav', 'ref_wav': '/Users/mac/pyvideotrans/tmp/73926/719b376297/clone-0.wav'
......
, 'endraw': '00:01:55,460', 'ref_text': "we're not climbing back. Then they'll slow me down. you", 'start_time_source': 96600, 'end_time_source': 115460, 'role': 'clone', 'rate': '+0%', 'volume': '+0%', 'pitch': '+0Hz', 'tts_type': 2, 'filename': '/Users/mac/pyvideotrans/tmp/73926/719b376297/10-7c1792372c1fd97e37f23253114bde16.wav', 'ref_wav': '/Users/mac/pyvideotrans/tmp/73926/719b376297/clone-10.wav', 'ref_language': 'en'}
[DEBUG] self.volume='+0%', self.rate='+0%', self.pitch='+0Hz'
[DEBUG] 当前使用配音渠道:F5-TTS(Built-in)
[DEBUG] app_cfg.proxy=None
[DEBUG] 无法连接 huggingface.co, 使用镜像替换: hf-mirror.com
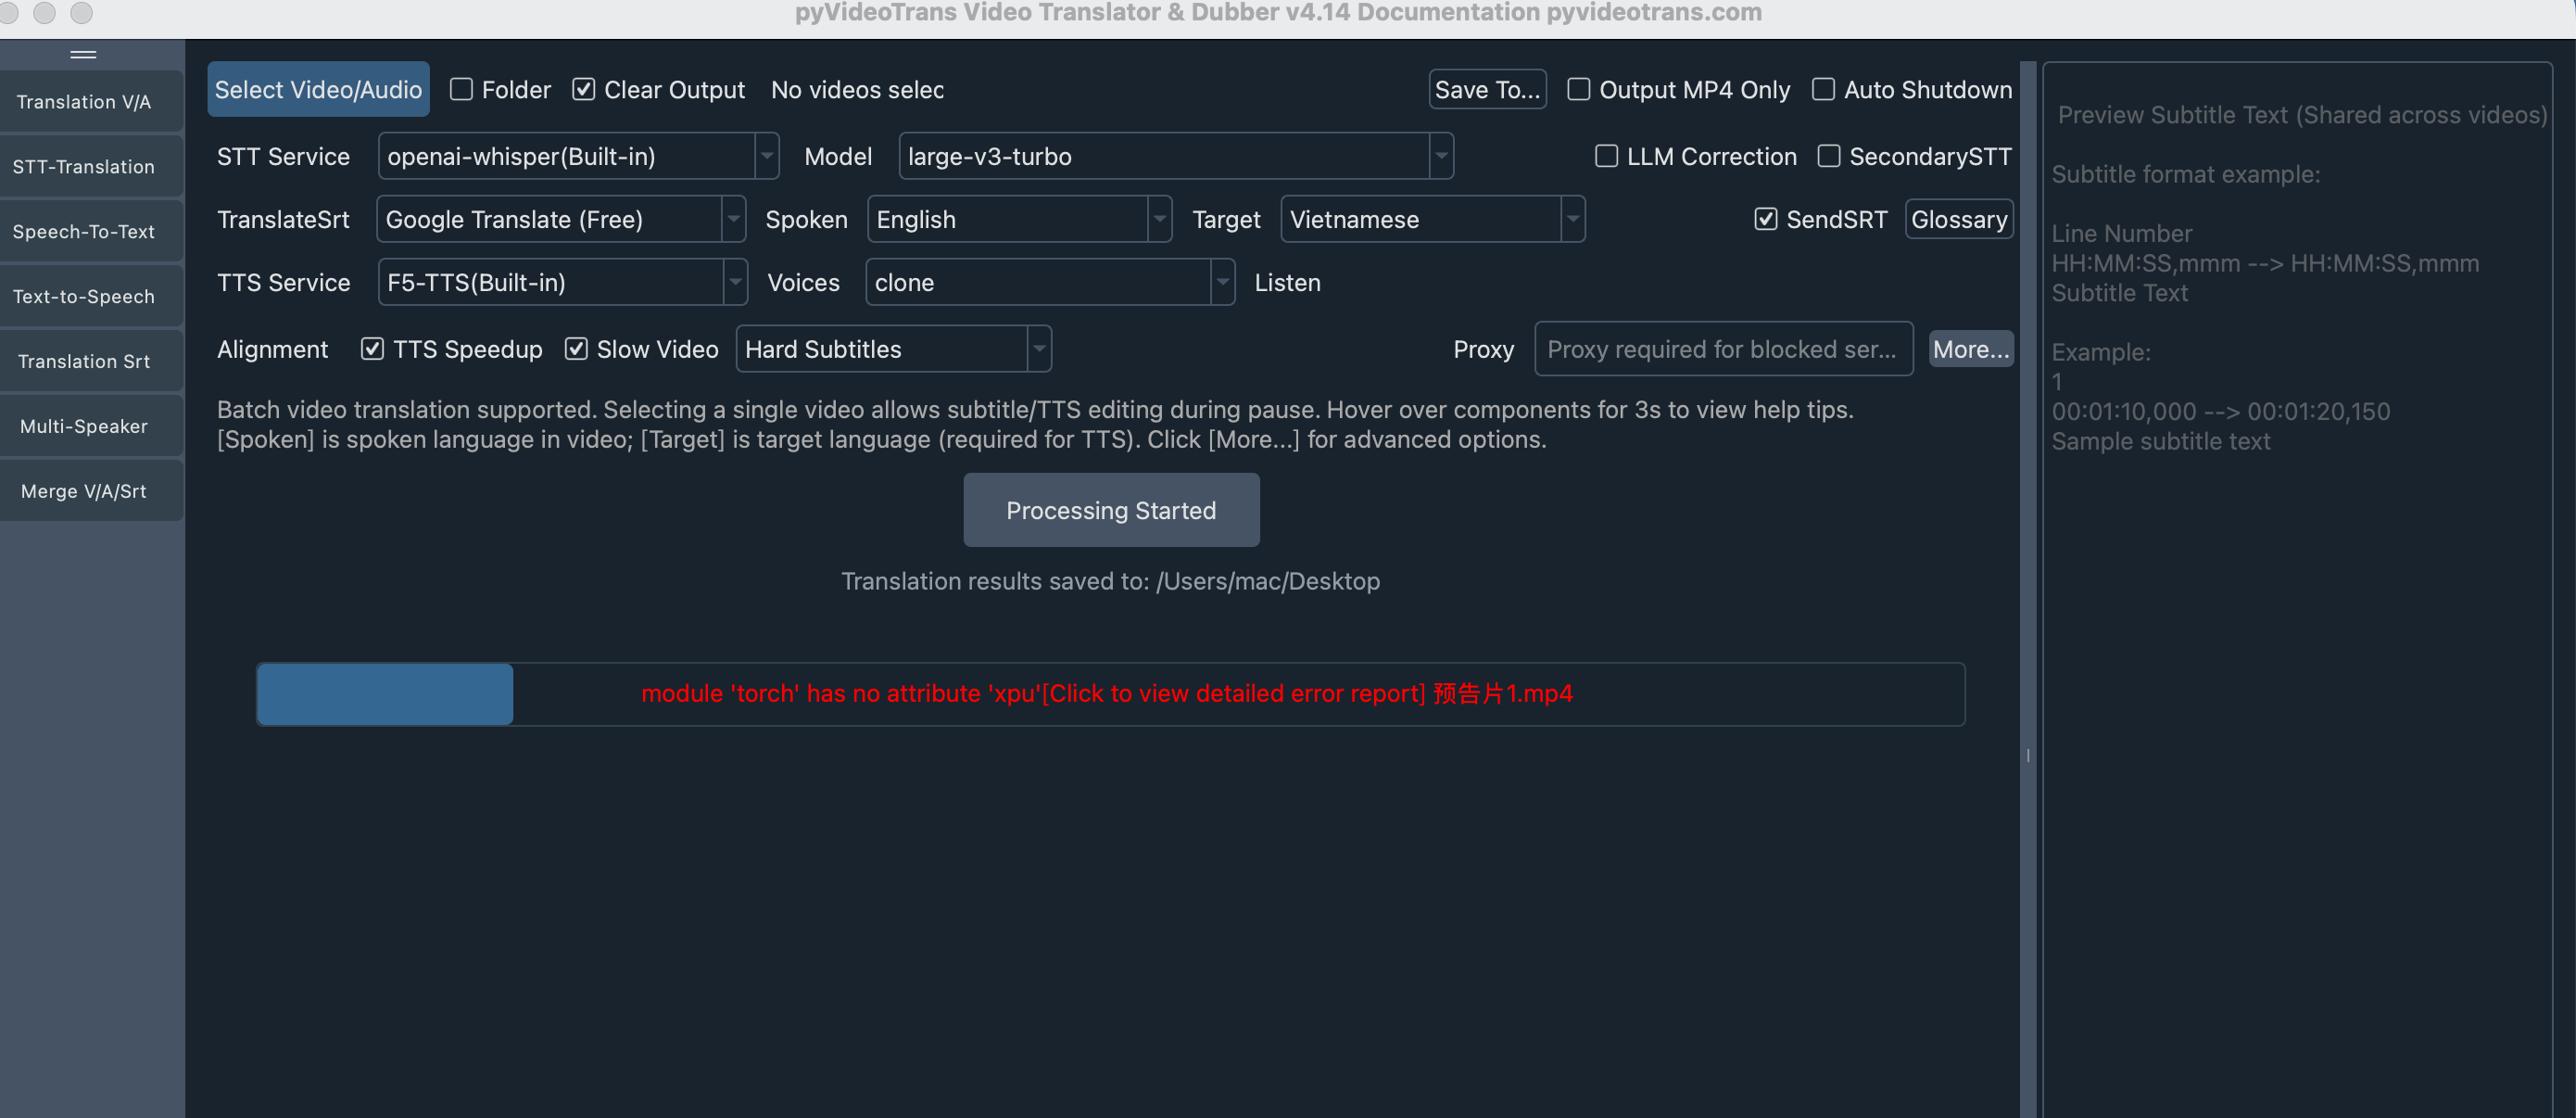
[ERROR] 单视频模式翻译失败module 'torch' has no attribute 'xpu'
Traceback (most recent call last):
File "/Users/mac/pyvideotrans/videotrans/task/only_one.py", line 107, in run

trk.dubbing()

File "/Users/mac/pyvideotrans/videotrans/task/_stage_dubbing.py", line 24, in dubbing

self._tts()

File "/Users/mac/pyvideotrans/videotrans/task/_stage_dubbing.py", line 101, in _tts

run_tts(

File "/Users/mac/pyvideotrans/videotrans/tts/__init__.py", line 119, in run

return _cls(**kwargs).run()  # type:ignore

File "/Users/mac/pyvideotrans/videotrans/tts/_base.py", line 96, in run

self._exec()

File "/Users/mac/pyvideotrans/videotrans/tts/_f5tts.py", line 57, in _exec

from videotrans.process.f5_tts import f5tts_fun

File "/Users/mac/pyvideotrans/videotrans/process/f5_tts.py", line 23, in

from f5_tts.api import F5TTS

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/f5_tts/api.py", line 11, in

from f5_tts.infer.utils_infer import (

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/f5_tts/infer/utils_infer.py", line 42, in

if torch.xpu.is_available()

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/torch/__init__.py", line 1938, in getattr

raise AttributeError(f"module '{__name__}' has no attribute '{name}'")

AttributeError: module 'torch' has no attribute 'xpu'
3 Replies

#1 DeepSeek reply at 21 hours ago

这是由于当前安装的 f5-tts 库版本与 torch 版本不兼容导致的。

f5_tts 库的 utils_infer.py 代码中调用了 torch.xpu.is_available()(Intel XPU 检测接口),而您当前环境中的 PyTorch 版本不包含该属性,因此抛出 AttributeError。

故障分析:

  • 报错位置在第三方库 f5_tts 内部(.venv/lib/python3.10/site-packages/f5_tts/infer/utils_infer.py 第 42 行),而非 pyVideoTrans 主程序。

  • torch.xpu 是较新版本 PyTorch 才提供的 Intel GPU 检测接口。

    当安装的 f5-tts 要求较新的 torch,但实际环境中的 torch 版本较旧时,就会触发该错误。

解决方案(任选其一,按推荐度排序):

  1. 升级 PyTorch 到包含 XPU 支持的版本(macOS 上通常是 CPU 版 torch):

    uv sync --upgrade-package torch

    或重新执行完整依赖同步:

    uv sync
  2. 改用其他配音渠道:在配音渠道下拉框中,将 F5-TTS(内置) 更换为 Edge-TTS(免费)、Qwen3-TTS(内置) 或 OmniVoice-TTS 等其他支持声音克隆的渠道,可绕过该库兼容问题。

  3. 升级到最新版本 pyVideoTrans:v4.12 中明确提到升级了 transformers 到 5.13.1,并优化了本地配音渠道的兼容性,建议先升级到 v4.12 或 v4.14 再试。

补充提示:日志中 [WARNING] 检测google翻译失败:status_code=0 是正常的回退逻辑(已自动切换微软翻译,未影响任务)。

真正的失败点是 F5-TTS 加载阶段。

如果以上方法均无效,请提供以下信息以便进一步排查:

  • 软件版本号(v4.xx)
  • 当前 torch 版本:终端执行 uv run python -c "import torch; print(torch.__version__)"
  • 当前 f5-tts 版本:uv pip show f5-tts

请查阅相关文档:

#2 194.56**4 reply at 21 hours ago

[DEBUG] [新进程任务 结束:title='Qwen3-TTS dubbing...'],耗时21.99173617362976s
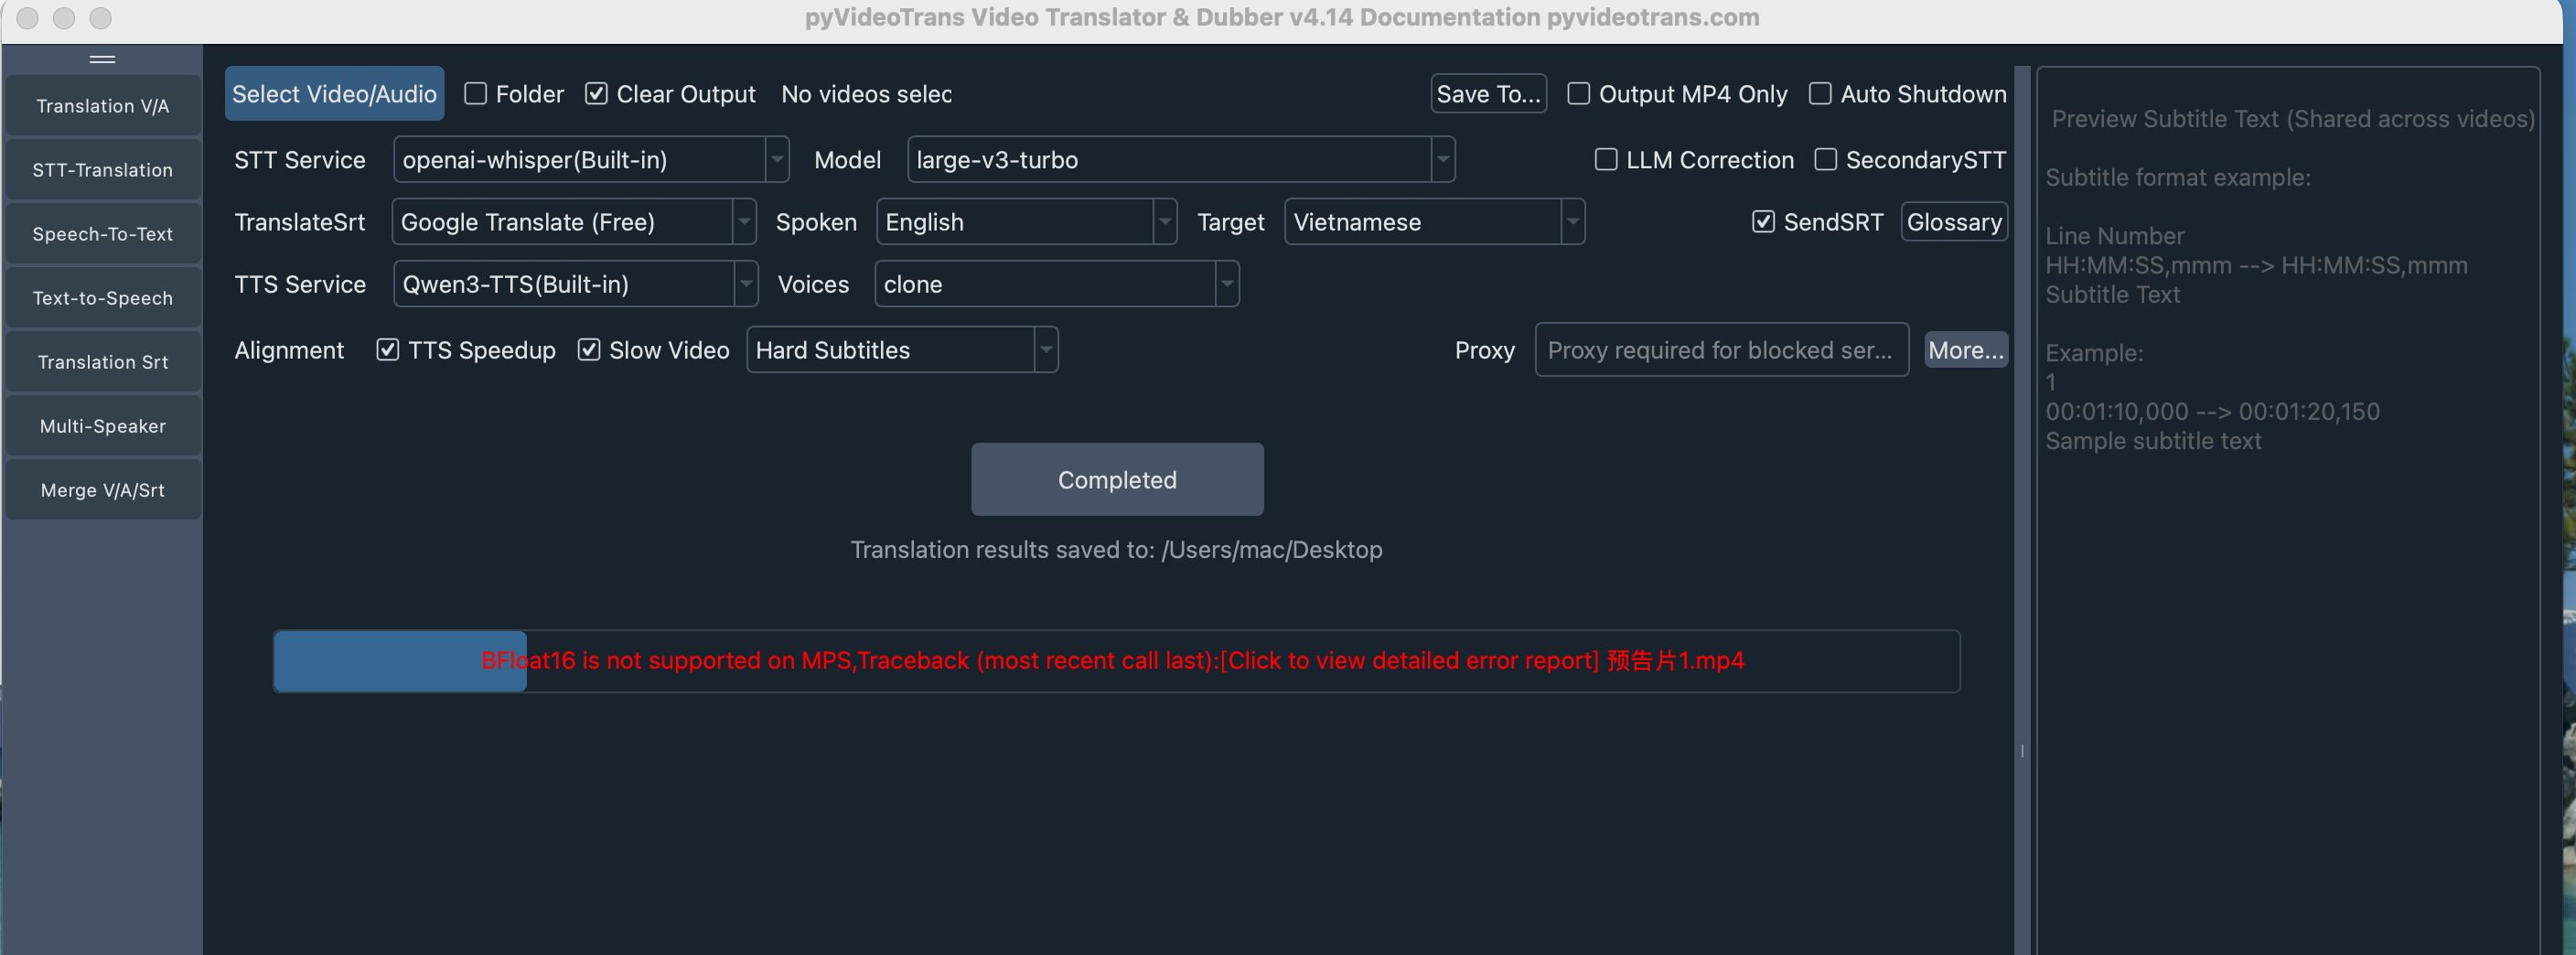
[ERROR] 单视频模式翻译失败BFloat16 is not supported on MPS,Traceback (most recent call last):
File "/Users/mac/pyvideotrans/videotrans/process/qwen_tts.py", line 63, in qwen3tts_fun

BASE_OBJ = Qwen3TTSModel.from_pretrained(

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/qwen_tts/inference/qwen3_tts_model.py", line 112, in from_pretrained

model = AutoModel.from_pretrained(pretrained_model_name_or_path, **kwargs)

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/transformers4576/models/auto/auto_factory.py", line 604, in from_pretrained

return model_class.from_pretrained(

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/qwen_tts/core/models/modeling_qwen3_tts.py", line 1876, in from_pretrained

model = super().from_pretrained(

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/transformers4576/modeling_utils.py", line 277, in _wrapp
......
VideoTransError(err)
videotrans.configure.excepts.VideoTransError: BFloat16 is not supported on MPS,Traceback (most recent call last):
File "/Users/mac/pyvideotrans/videotrans/process/qwen_tts.py", line 63, in qwen3tts_fun

BASE_OBJ = Qwen3TTSModel.from_pretrained(

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/qwen_tts/inference/qwen3_tts_model.py", line 112, in from_pretrained

model = AutoModel.from_pretrained(pretrained_model_name_or_path, **kwargs)

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/transformers4576/models/auto/auto_factory.py", line 604, in from_pretrained

return model_class.from_pretrained(

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/qwen_tts/core/models/modeling_qwen3_tts.py", line 1876, in from_pretrained

model = super().from_pretrained(

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/transformers4576/modeling_utils.py", line 277, in _wrapper

return func(*args, **kwargs)

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/transformers4576/modeling_utils.py", line 5044, in from_pretrained

) = cls._load_pretrained_model(

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/transformers4576/modeling_utils.py", line 5464, in _load_pretrained_model

_error_msgs, disk-*** = load_shard_file(args)

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/transformers4576/modeling_utils.py", line 843, in load_shard_file

disk-*** = _load_state_dict_into_meta_model(

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/torch/utils/_contextlib.py", line 115, in decorate_context

return func(*args, **kwargs)

File "/Users/mac/pyvideotrans/.venv/lib/python3.10/site-packages/transformers4576/modeling_utils.py", line 748, in _load_state_dict_into_meta_model

param = param[...]

TypeError: BFloat16 is not supported on MPS

image

#3 DeepSeek reply at 21 hours ago

这是因为 Qwen3-TTS 内置渠道在 macOS 上尝试使用 MPS(Apple 芯片 GPU 加速)加载模型,但 Apple MPS 后端不支持 BFloat16 数据类型,导致模型加载失败。

故障定位:报错 TypeError: BFloat16 is not supported on MPS,发生在 qwen_tts 模型 from_pretrained 阶段,即模型下载后加载到 MPS 设备时数据类型不兼容。

解决方案(按推荐度排序):强制让 Qwen3-TTS 在 CPU 上运行(MPS 不支持 bfloat16,CPU 支持):由于 Qwen3-TTS 属于"优先使用 GPU"的渠道,macOS 上会优先尝试 MPS。

可通过设置环境变量强制其回退到 CPU,在启动软件前于终端执行:export PYTORCH_ENABLE_MPS_FALLBACK=1export CUDA_VISIBLE_DEVICES=""然后 uv run sp.py 启动。

若无效,则需要修改 videotrans/process/qwen_tts.py 第 63 行附近的 from_pretrained 调用,显式添加 torch_dtype=torch.float32 参数并指定设备为 CPU。

更换配音渠道(推荐,省事):macOS 上使用 Qwen3-TTS 兼容性较差。

建议改用其他支持声音克隆且兼容性好的渠道:Edge-TTS(免费):不支持克隆但最稳定OmniVoice-TTS(内置):支持所有语言克隆,跨平台兼容性好F5-TTS(内置):中英克隆(需先解决上一轮的 torch 版本问题)Confucius-TTS(内置):14 种语言克隆改进程池管理:进入 菜单 → 工具/选项 → 高级选项 → 通用设置,将 强制指定重型任务运行设备 改为 CPU 相关选项,避免自动分配 MPS。

补充说明:该问题属于 PyTorch 生态在 macOS MPS 后端对 bfloat16 支持的长期限制,并非 pyVideoTrans 的 bug。

若需确认最新是否已修复,可尝试升级到 v4.14(v4.13 日志提到"Qwen-TTS/Higgs等本地配音渠道放弃8位量化,避免某些环境下兼容问题",但未明确针对 MPS+bfloat16)。

请查阅相关文档:
Qwen3-TTS(内置)使用说明
全部配音渠道说明
MacOS/Linux 安装

Thinking...
Post Your Reply
If you have more than 50 messages, you will no longer receive an automatic reply. Please ask a new question!
Open source and free maintenance is not easy. If this project is helpful to you, please consider making a small donation to help the project continue to maintain and update.

Dondate via ko-fi.com

Related resource